Blog 26 October 2026 · 6 min read
Automatic problem detection with learned baselines
How Obscenter judges every measurement against its own last three days, opens one ticket per fault, and closes it by itself when things are normal again.
Most monitoring products start with a form: pick a metric, type a threshold, choose who to wake. Six months later the thresholds are wrong for half the services, the pager fires at every deploy, and somebody has quietly muted the channel. The problem was never the form. It was asking people to guess, in advance, what "too slow" means for every service they run.
Obscenter does not ask. Its detection engine compares each measurement with that same measurement's own recent past, opens a ticket when the two disagree, and explains in numbers why it did. This article covers how that comparison works and what keeps it quiet.
Why fixed alert thresholds fail
"Slower than 500 ms is bad" is wrong on every install. On a search service that normally answers in 40 ms it is blind to a tenfold slowdown. On a report generator that normally takes four seconds it fires all day. The same is true of error rates, request volumes and most of what a system produces. A single number for everything is either too loud or too deaf, and usually both at once on different services.
So in Obscenter the threshold is the baseline. Most measurements are compared with their own last three days, in ten-minute buckets. A thing needs at least two hours of history before it is compared with itself; until then, only absolute rules apply.
Median and MAD, not mean and standard deviation
The comparison uses the median and the median absolute deviation (MAD) rather than the mean and the standard deviation. The reason is practical: a single outage inside the baseline window drags a mean far enough to hide the next outage. A median does not move for one bad hour. The MAD is scaled so that it reads like a standard deviation, which keeps the "how unusual is this" number familiar.
Absolute limits exist only where a number means something on its own. A disk at 96% is full whatever it did last week, so disk, memory and CPU saturation have fixed warning, serious and critical lines, judged on ten-minute averages over at least three samples.
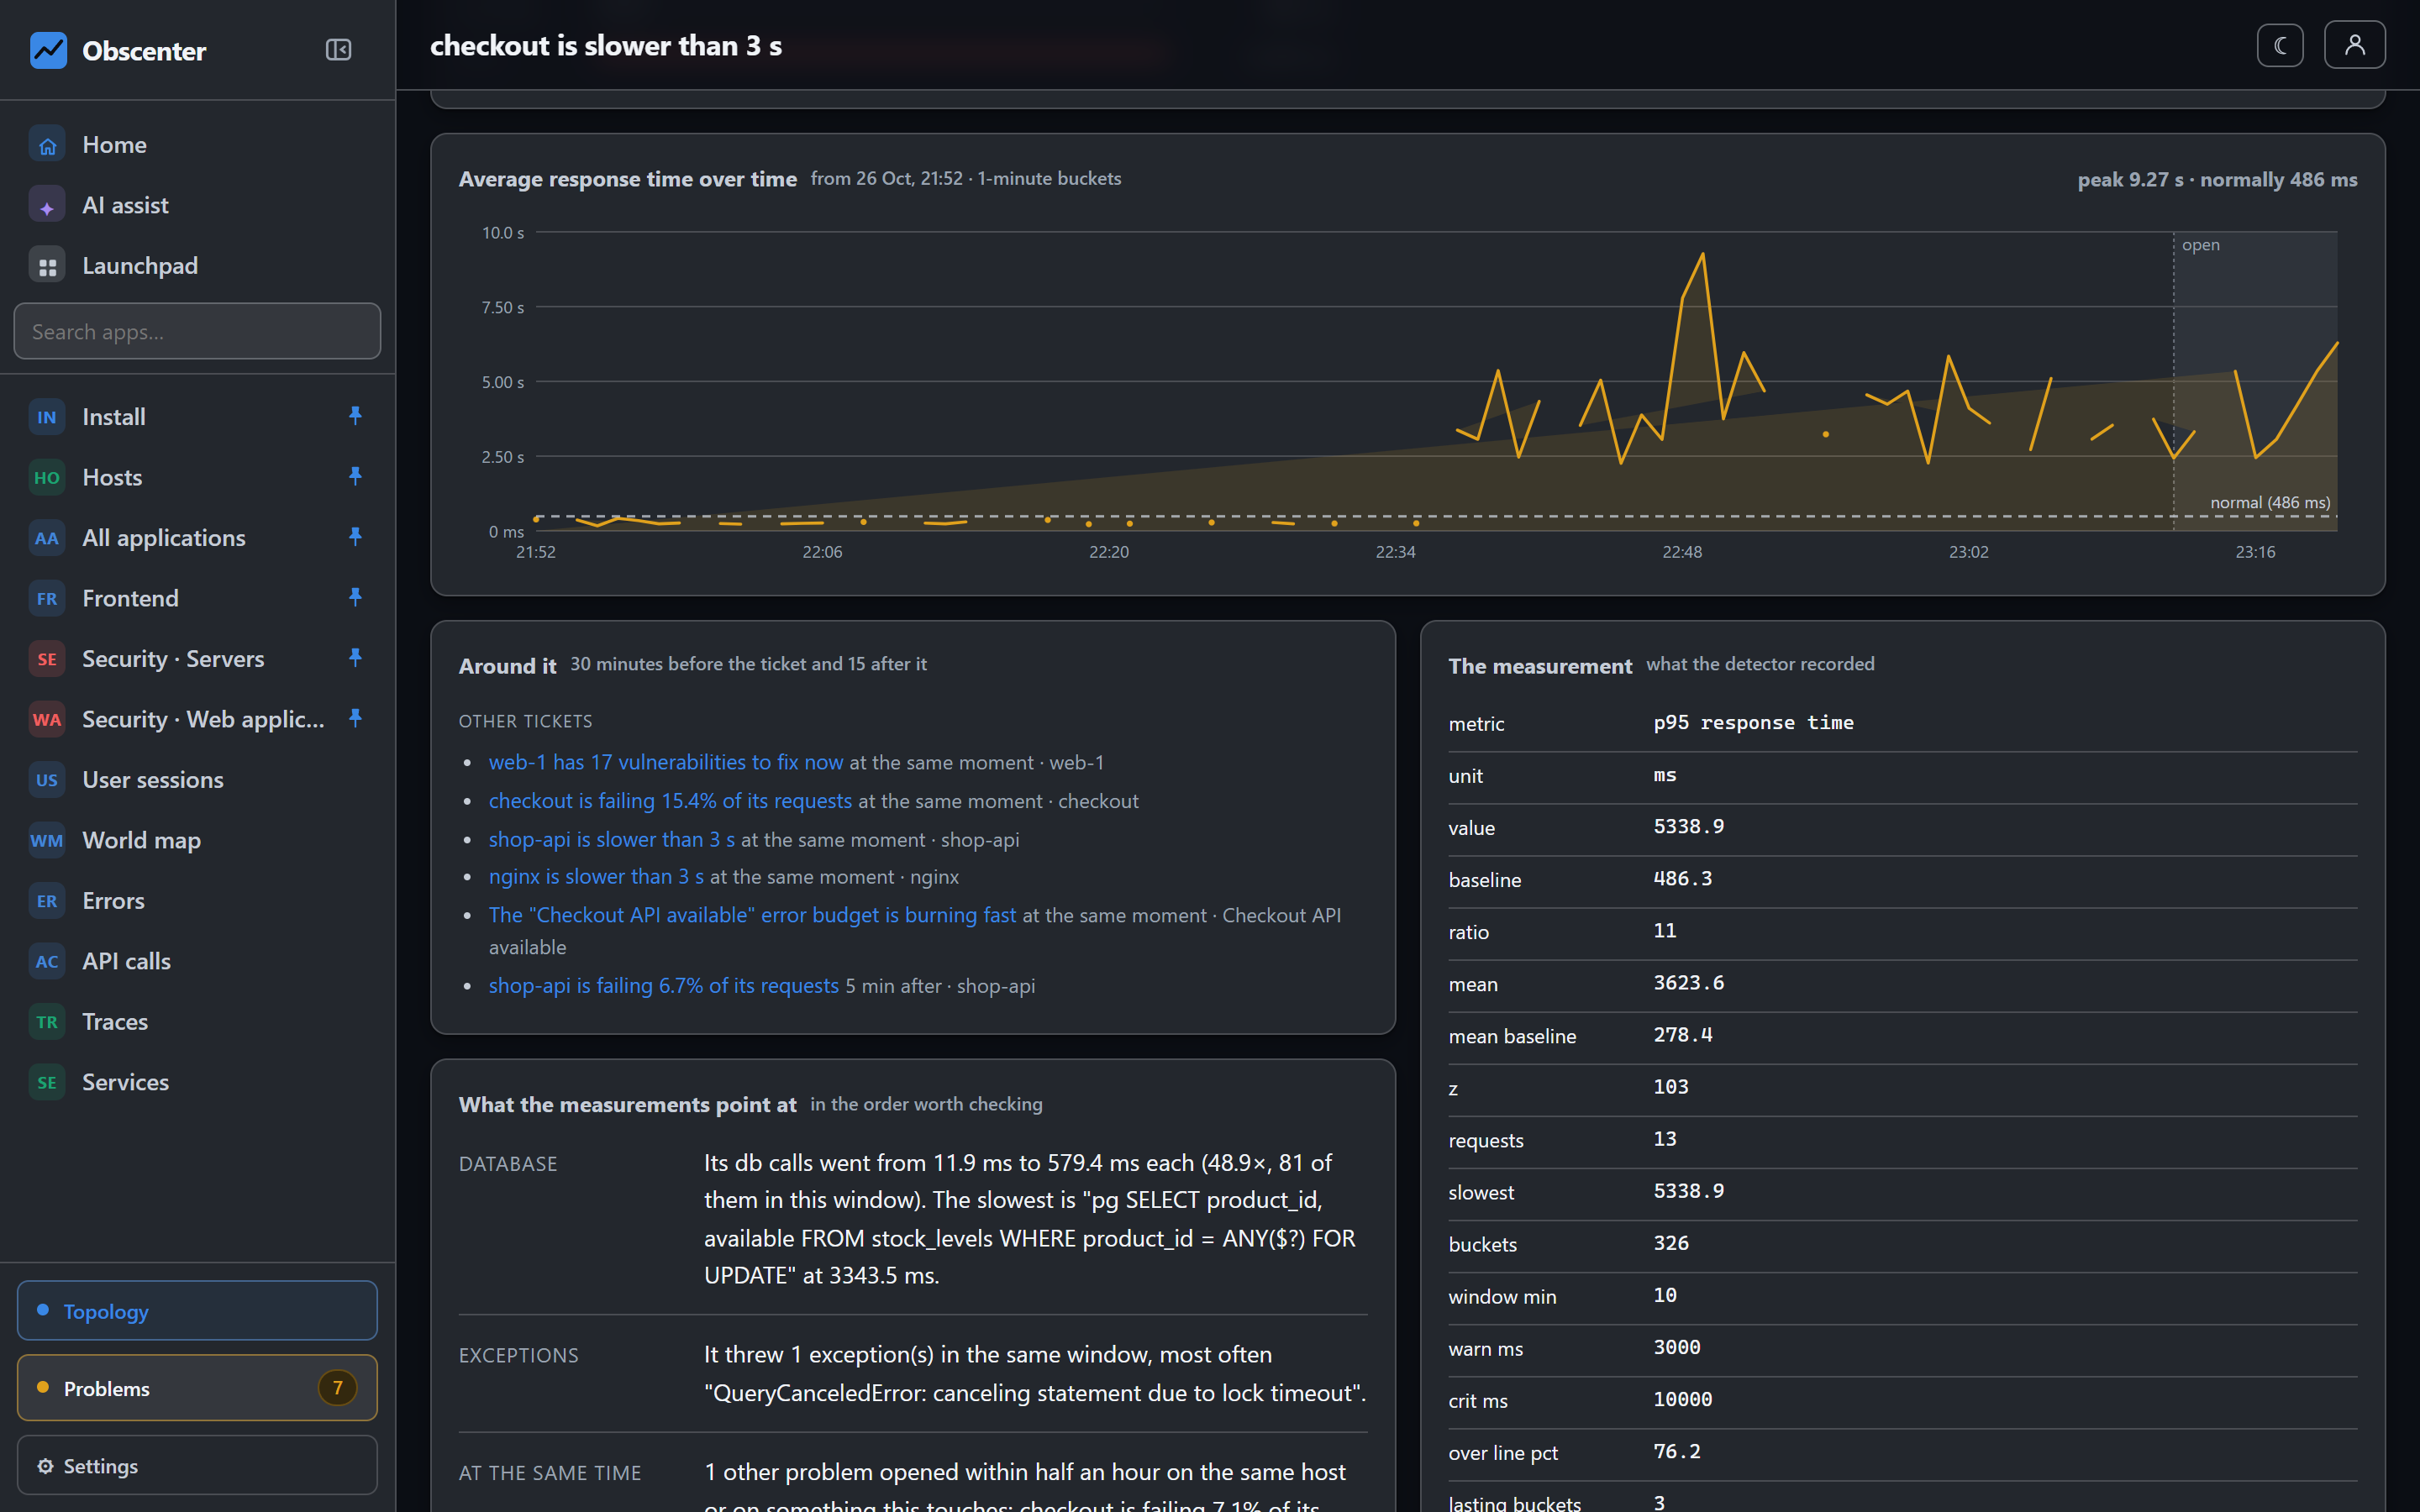
Quiet by construction: three conditions for a slow service
A relative rule alone is noisy too. A service that normally answers in 100 ms and once takes 800 ms is "eight times slower" and nobody's outage. So a latency ticket needs three things at once:
- Over a line a person chose. Each application has a Fine up to line, 3 s by default, and a Critical above line, 10 s by default. Below the first, no ticket, whatever the ratio says.
- Felt or lasting. A real share of requests crossed the line, or it stayed over it across buckets. One slow request among a hundred fast ones is not a ticket.
- Worse than usual, or plainly bad. Either the p95 moved against its own history — twice the baseline and statistically unusual — or it is past the critical line, which is a ticket even for a service that has always been that slow.
The other detectors follow the same idea. An error rate is judged against the service's own rate, or opens on its own at 20% with no history. Browser errors are judged against the application's normal, and the ticket says how many of the error types are brand new. A service that stops reporting is judged against its own usual gaps, not a global timeout.
One ticket per fault, closed by itself
The engine runs every two minutes. What it produces is a ticket, not an alert stream:
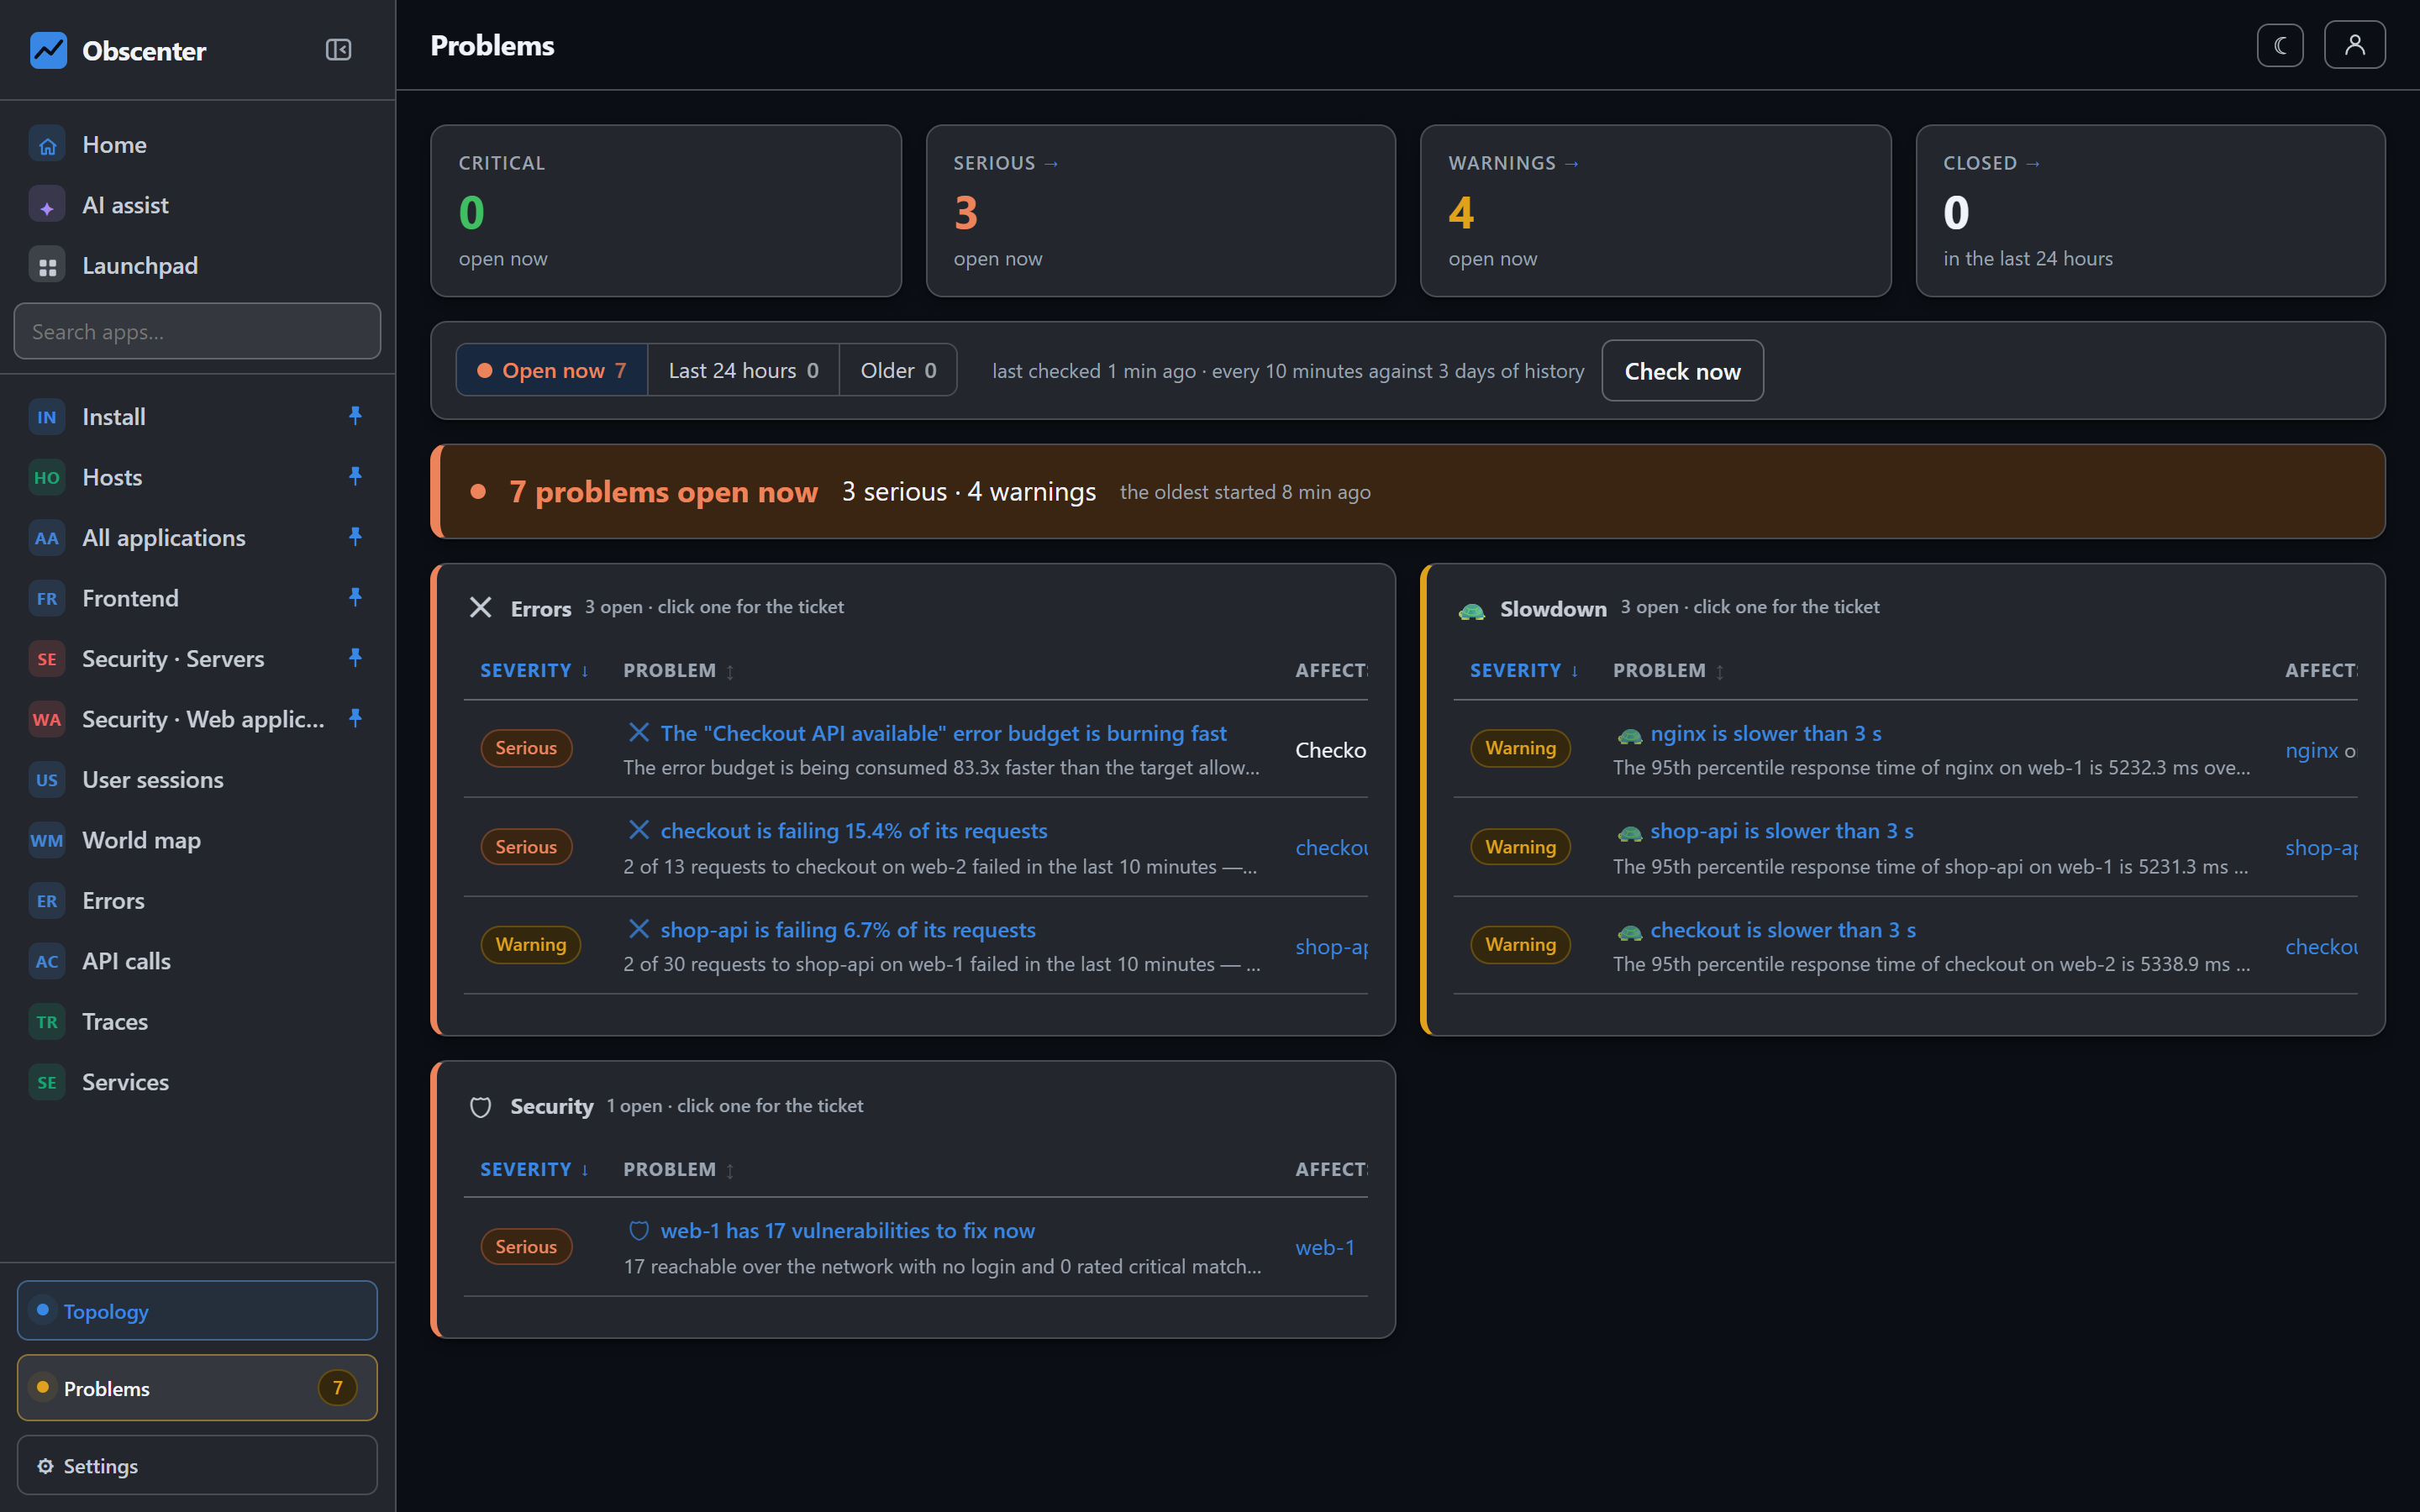
- A problem opens once and keeps its identity for as long as the fault lasts, however many times the scan sees it.
- When several detectors see the same fault, their findings are merged and the most severe is kept.
- If the fault gets worse, the severity rises, the cause is worked out again, and the escalation is notified. An open ticket never quietly gets better.
- When the measurement has been back to normal for 30 minutes, the ticket closes itself and records how long it lasted.
Severities are warning, serious and critical, and notification policies decide who hears about which. That is covered in the article on root cause and alert routing.
What the engine watches
Detection covers every layer the product measures:
- Services: slow responses, failing requests, bursts of exceptions, a service that goes quiet, a blocked or saturated event loop, a heap growing on a straight line.
- Machines: CPU, memory, swap, disk per mount, TCP retransmissions, major page faults, a machine whose agent stops reporting, watched ports with nothing listening.
- Processes and containers: file descriptors near the limit, thread counts that keep growing, containers near their memory limit or heavily throttled.
- Databases: deadlocks, rollbacks and a falling cache hit ratio.
- Visitors: rising browser errors, Core Web Vitals that are poor at p75, rage and dead clicks across sessions, and a traffic collapse.
- Checks, objectives, security and devices: failing synthetic checks, expiring certificates, burning error budgets, exploited vulnerabilities, password guessing, logins from new places, and IoT devices that stop sending.
Every measured column in the product is either registered with the detector that watches it, or carries a written reason why it deliberately does not alert. The build fails on a column that is in neither list. Not alerting is often the right answer — a threshold that fires on healthy machines is how monitoring gets switched off — but it has to be a decision somebody wrote down.
Tested for silence, not just for firing
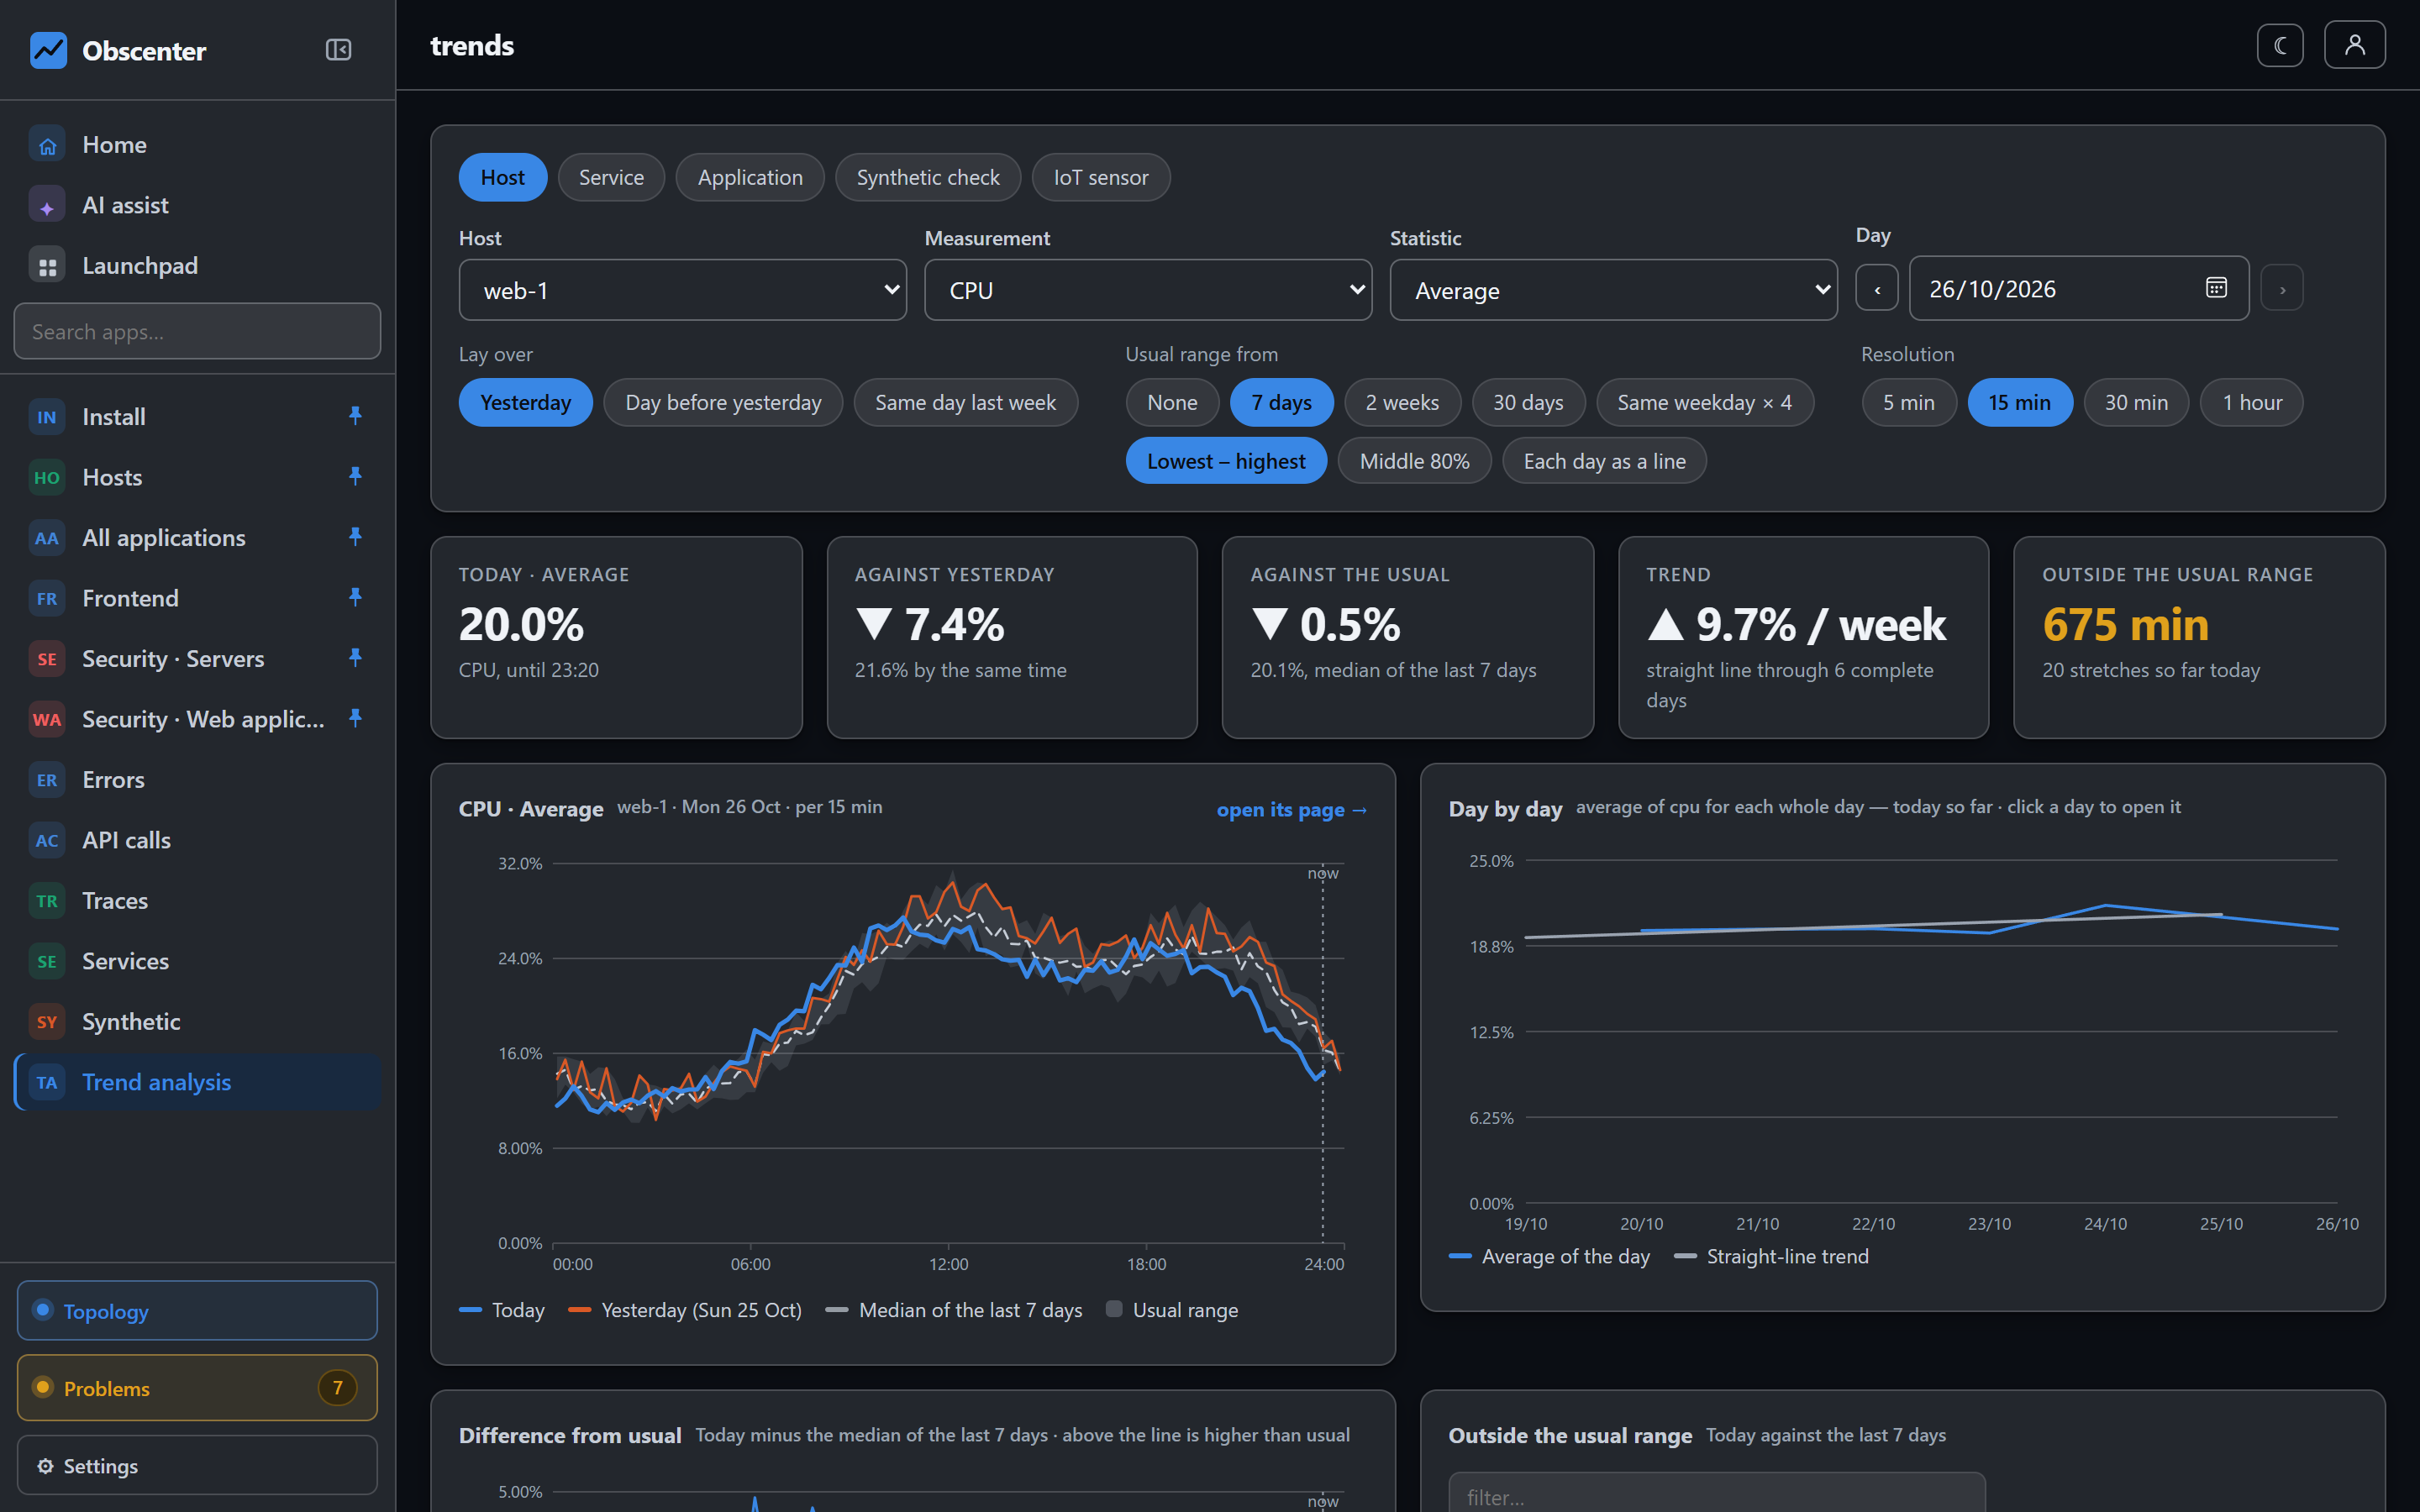
A detector that fires is trivial. The value of an alerting engine is in when it stays quiet. So every detector is tested the same way: build a healthy world, check that nothing fires, break exactly one thing, and check that the right ticket opens. One slow request among a hundred fast ones does not open a ticket; a shifted distribution does. A process that started a minute ago and stopped — the shape of every test run and deploy — does not open a "stopped reporting" ticket; a service that has run for days does.
The product applies the same honesty to itself. For 15 minutes after Obscenter restarts — a deploy, or its own machine rebooting — findings about its own parts are capped at warning, with a note saying why. The monitor restarting is not your outage.
No model decides
Detection is arithmetic on stored rows. No language model takes part in deciding whether something is wrong, and every ticket can be recomputed from the rows it names, which is what makes it arguable. If you configure a model, it can explain a ticket afterwards; it can never open, suppress or rank one.
What you can tune
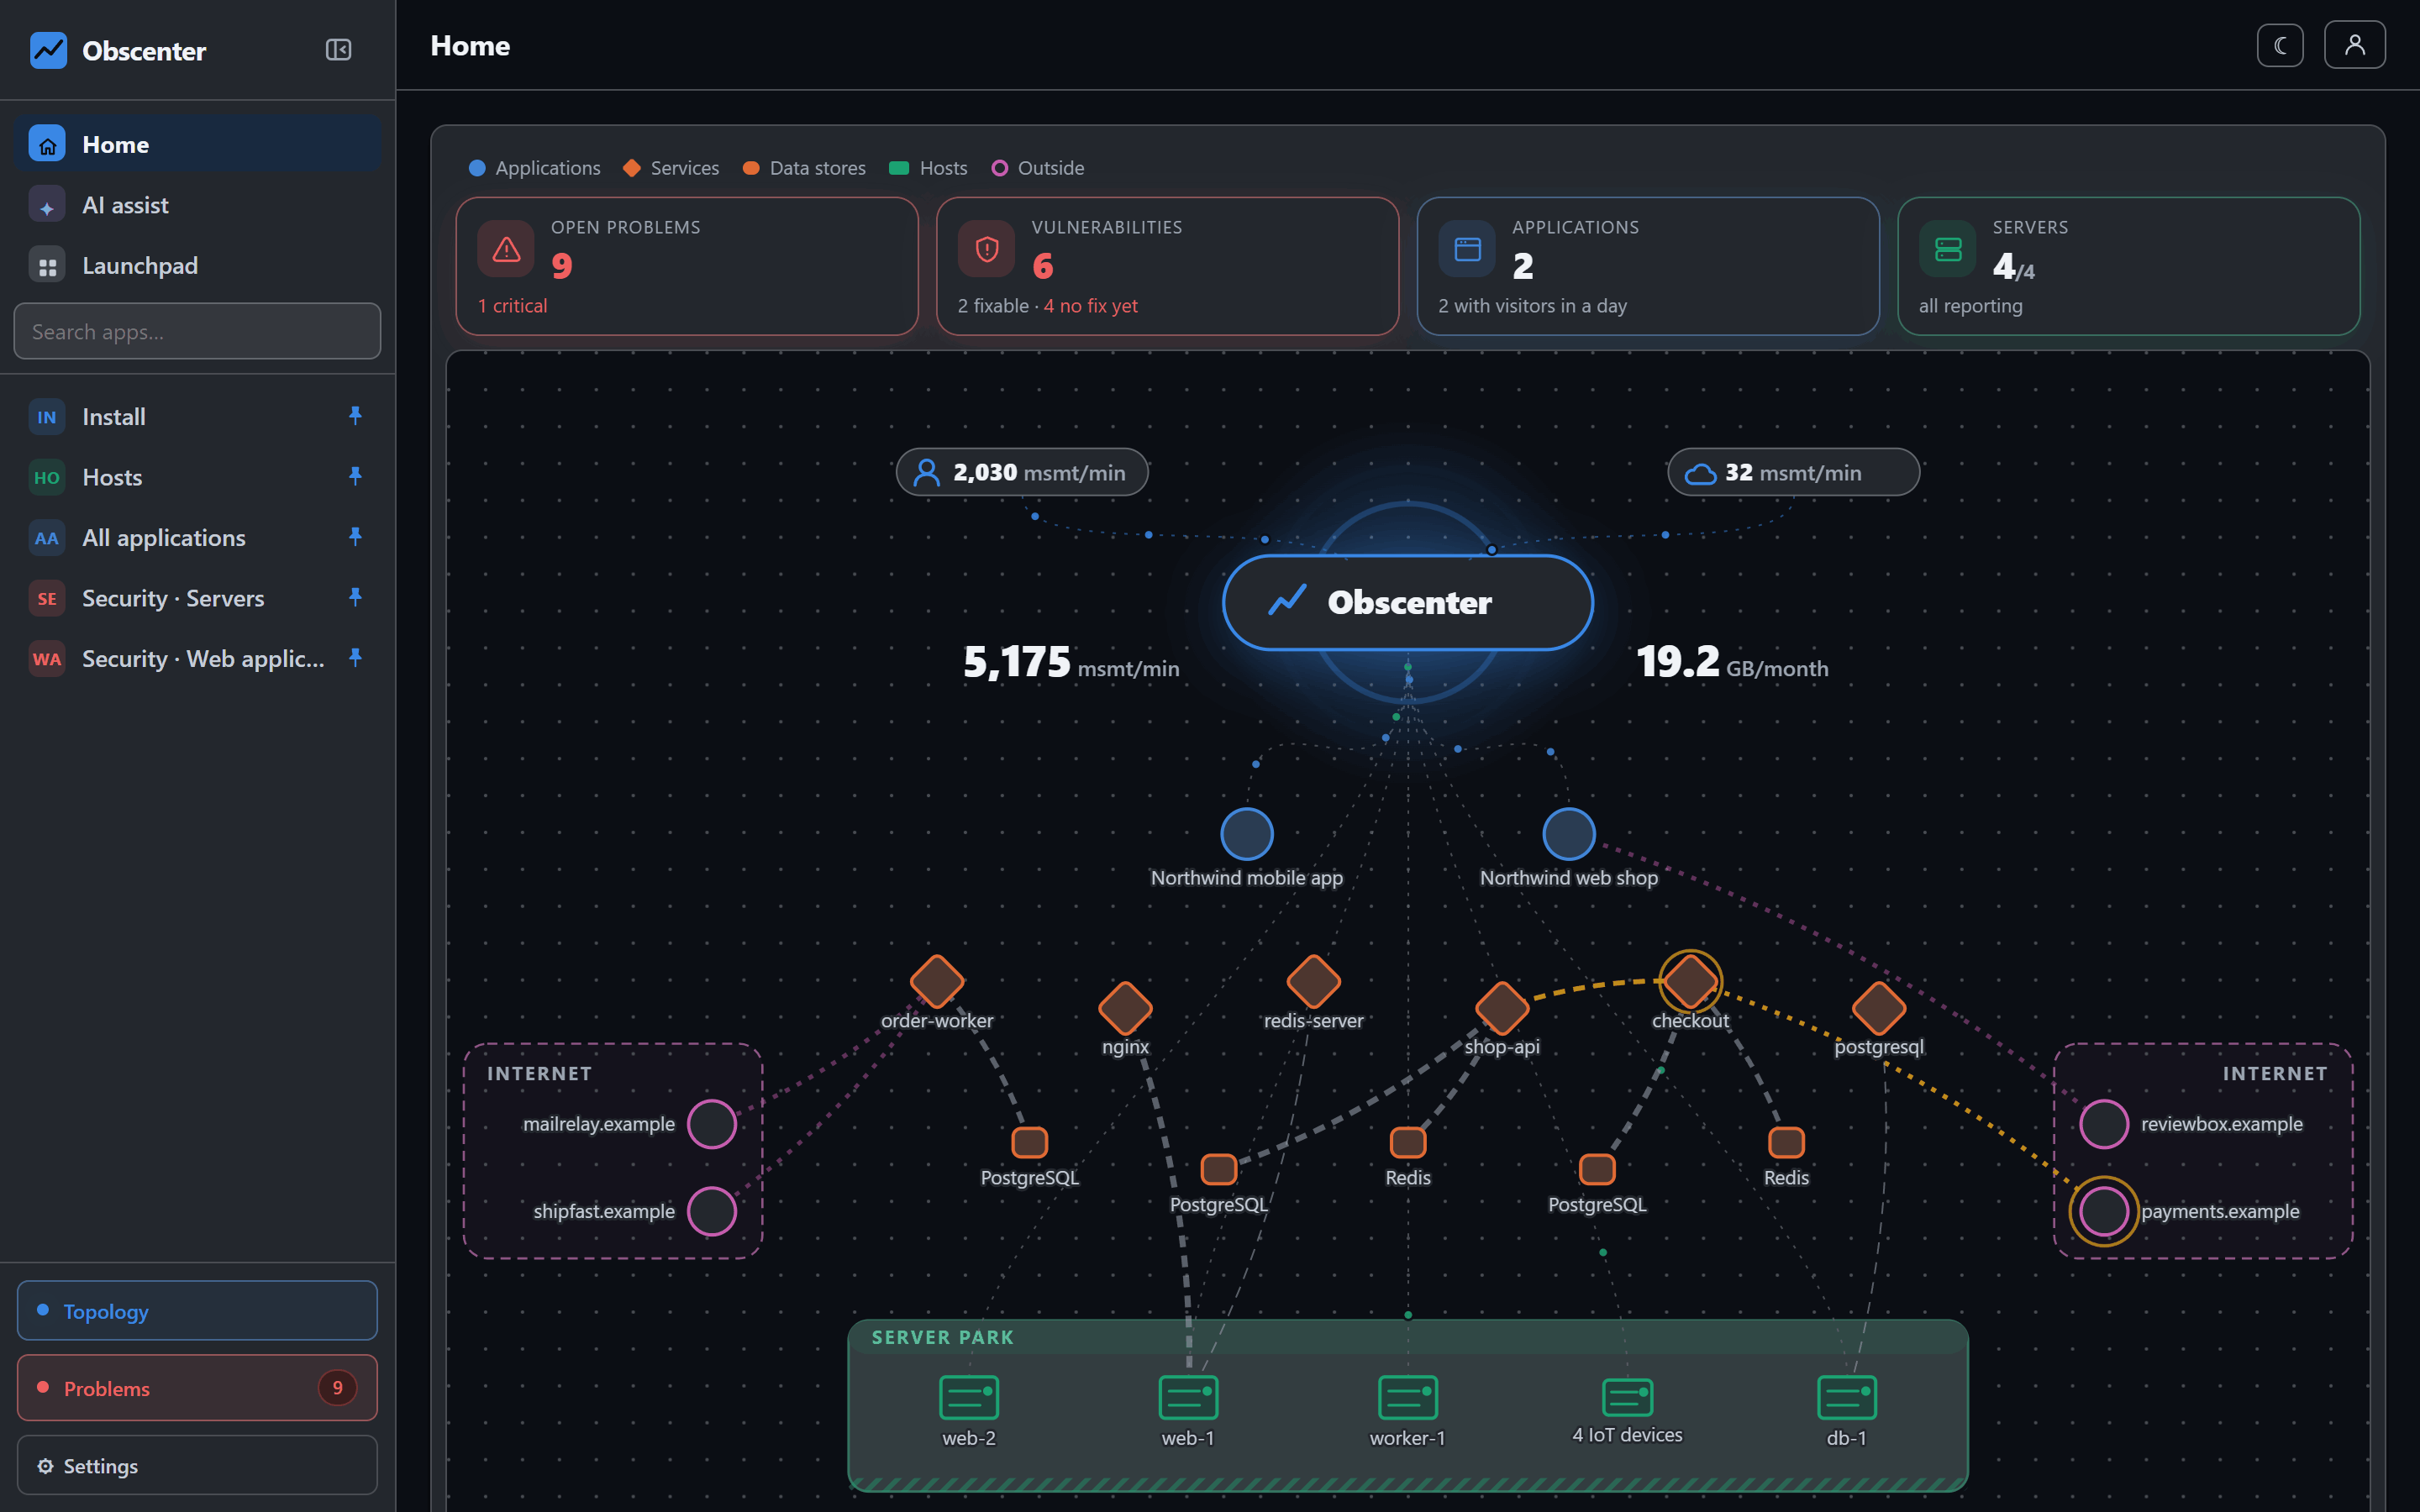
- Each application's two slow lines, under its settings. The AI assistant can propose values, as a button you press.
- Mute a noisy service, host or entity by name; its tickets still open, they just never notify.
- Maintenance windows for the whole install or one machine.
- Notification policies: severity floors, categories and scope.
The full list of detectors and their thresholds is in How problem detection works, and the ticket page is described in Root cause, timeline and the ticket.
Let it learn your normal
Baselines need a few days of history, so the sooner the agent and the tag are in, the sooner the engine knows what normal looks like for your systems.
Start free or read Getting started.